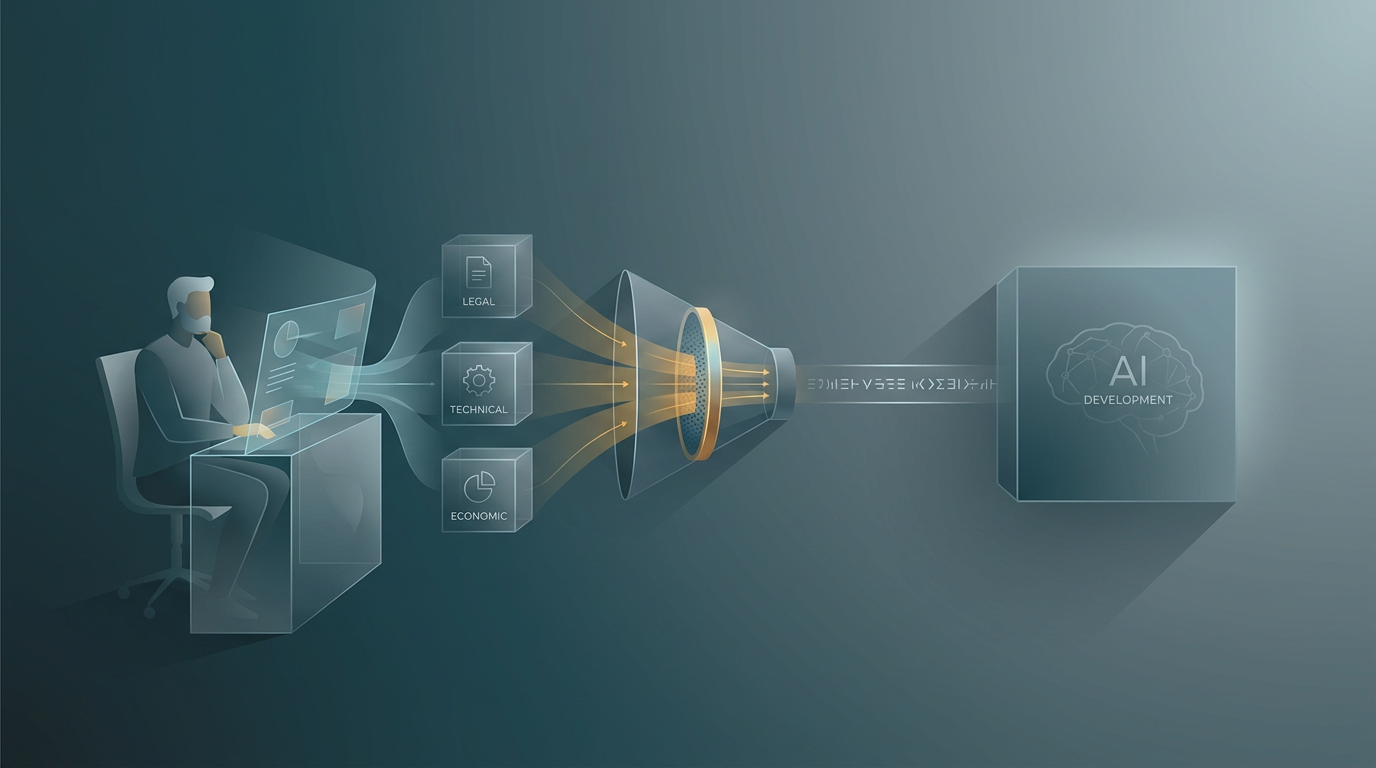
How to Validate Data Feasibility for AI Products
To build a viable AI product, you must prove you can legally, technically, and economically acquire the necessary training and operational data before writing a single line of code. Many early-stage founders confuse market demand—whether users want the AI solution—with data feasibility, which dictates whether the AI can actually be built. Without a secure, high-quality data pipeline, even the most brilliant AI concept will fail in execution.
This guide breaks down how to test data feasibility using a structured evaluation methodology.
Why Data Feasibility Precedes AI Development
Before scoping your MVP for technical feasibility, you must answer the fundamental question: Can you get the data?
AI models require specific, structured inputs to generate valuable outputs. If you assume you can scrape a competitor's site, rely on a free API that might be deprecated, or ask users to manually upload complex datasets, you introduce fatal platform risks. Validating data access early prevents wasted engineering cycles.
The 6-Point Data Feasibility Framework
Evaluate your AI product idea against these six critical dimensions:
- Access Permission: Do you have the legal right, terms of service (ToS) compliance, and user consent to collect and process this data?
- Coverage: Does the available dataset cover the edge cases, demographics, and scenarios your model will encounter in the real world?
- Quality: Is the data structured, clean, and free from debilitating bias, or will it require massive manual cleaning?
- Freshness: Does your product require real-time data to be useful, and can your pipeline support that latency?
- Labeling: Is the data already categorized, or will you need to pay subject matter experts to label it before training?
- Representative Sample: Can you manually acquire a small, representative sample today to test your assumptions?
Data Feasibility Worksheet
Use this decision table to evaluate your startup's data strategy. If you score "High Risk" in multiple categories, you must pivot your data acquisition strategy before building.
| Evaluation Criteria | Low Risk (Ideal) | High Risk (Red Flag) |
|---|---|---|
| Access Permission | Proprietary internal data or clear commercial API agreements | Relying on unapproved web scraping or violating third-party ToS |
| Coverage | Comprehensive dataset covering primary user scenarios | Highly fragmented data missing key demographics or edge cases |
| Quality | Highly structured, standardized formats (e.g., clean JSON/CSV) | Unstructured, messy formats (e.g., scanned PDFs, handwritten notes) |
| Freshness | Batch updates are acceptable for the user experience | Requires sub-second real-time streaming without a reliable provider |
| Labeling | Data is self-labeling (user actions create labels) | Requires expensive, manual annotation by domain experts |
| Sample Availability | Can download 1,000+ rows today to test prompts | Data is locked behind enterprise sales cycles or impossible to sample |
Worked Example: Hypothetical AI Legal Assistant
To illustrate this framework, let us apply it to a hypothetical startup building an AI tool to summarize commercial real estate leases.
- Access Permission: The founders plan to ask initial beta testers to upload their own leases. Risk: Medium. Users may be hesitant to share confidential documents due to NDAs.
- Coverage: The founders need leases from all 50 US states to account for regional legal variations. Risk: High. Starting out, they only have access to 10 leases from New York.
- Quality: Leases are often scanned PDFs with poor OCR readability. Risk: High. Cleaning the data will require significant preprocessing.
- Freshness: Leases do not change by the minute. Risk: Low. Batch processing is fine.
- Labeling: The AI needs to know what a "good" summary looks like. Risk: High. The founders must hire expensive real estate attorneys to grade the initial outputs.
- Sample Availability: The founders manually sourced 50 public commercial leases from SEC filings to test their initial prompts. Risk: Low.
Outcome: This hypothetical startup faces significant hurdles in Quality and Labeling. Before building the app, the founders must figure out a reliable OCR pipeline and secure a cost-effective way to label the data.
Key Takeaways
Testing data feasibility is a non-negotiable step for any AI startup. By systematically evaluating your data access, quality, and labeling requirements, you can identify architectural bottlenecks early. Once you have secured a viable data strategy, you can confidently move forward with defining your infrastructure using a technical architecture generator to map out your specific data pipelines and storage requirements.
Ready to apply this?
Idea OS evaluates your startup across market sizing, ICP, competition, and more—then generates strategic artifacts tailored to your evaluation.
Evaluate your idea first →New to Idea OS? Start by evaluating your idea.